 Knowledge Mesh
Retrieval is a permissions problem before relevance
The agent retrieved the right document for the wrong caller, and there is no delete for speech.
Voicing Team
8 min read
What happens between a caller finishing their sentence and a voice agent beginning its reply, in the order it happens.
Voicing Team9 min read
 Knowledge Mesh
A caller finishes a sentence. Somewhere under a second later, your agent starts talking.
Everything in this post happens in that gap. It is the most consequential and least examined interval in voice AI, and it’s where the difference between an agent that sounds impressive in a demo and one that survives a regulated production deployment is actually decided.
We’ve argued in three other posts that context is the binding constraint on enterprise voice AI: that context rot behaves differently in voice than in the coding agents the literature was written about, that a transcript is not a relationship, and that permission has to be enforced inside retrieval rather than after generation. This post is the mechanics underneath all three.
Let’s be precise, because “context layer” has become a term vendors apply to a wide range of things.
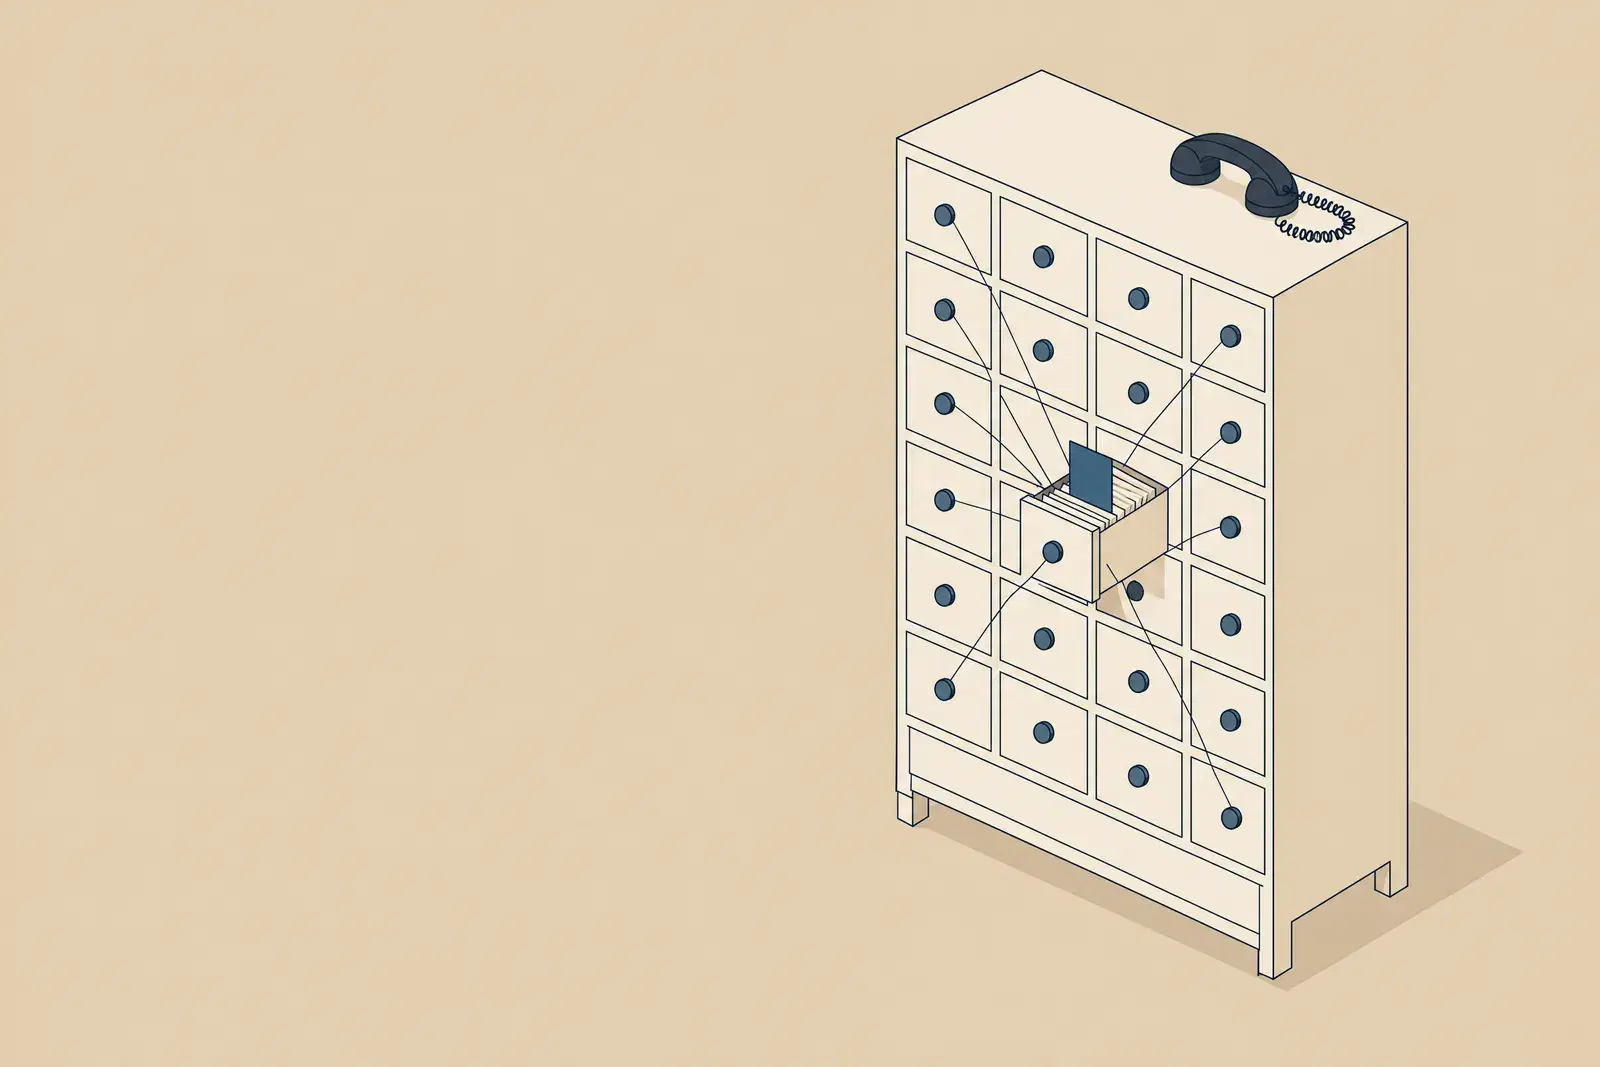
Knowledge Mesh is the retrieval and governance layer that decides what a voice agent knows on each conversational turn, assembling context from governed sources, enforcing permission at retrieval time, and delivering a resolved, cited, compact working set to the agent before it speaks.
What it isn’t: a general-purpose enterprise knowledge platform, a replacement for your data warehouse, or a system of record. It consumes your systems of record. It doesn’t become one.
That’s a narrower claim than the market’s current vocabulary invites, and we’d rather make the narrow one accurately.
Knowledge Mesh assembles context from three categories of input, and they behave differently enough that treating them the same is where most implementations go wrong.
Semantics: what things mean. The organised representation of your domain: how entities relate, what terms mean in your business, which concepts connect to which. This is what lets an agent understand that a caller asking about “my renewal” is asking about a specific contract with specific terms, rather than doing keyword matching against documents containing the word “renewal.”
Operational state: what is true right now. The live status of the entities in the conversation. Account standing, policy status, open tickets, current balance, verification state, what happened on the last call. This is the category most likely to be a naive implementation, because it’s the category that changes fastest and is most often loaded from a nightly sync rather than at conversation time.
Provenance: where it came from. For every fact delivered to the agent, the source, and the chain from source to answer. Not decoration. This is what makes the output auditable, and in a regulated deployment it’s frequently the difference between a system that clears risk review and one that doesn’t.
Semantics without operational state gives you an agent that understands your business and doesn’t know what’s happening in it. Operational state without semantics gives you an agent with live data it can’t reason about. Either without provenance gives you answers you can’t defend.
Inside the turn, three things happen in sequence.
The agent reasons over a working set the layer assembled. It does not keep its own accumulating history.
The agent needs to know something. The retrieval step determines what’s available to answer it.
Two properties matter here more than raw retrieval quality.
Permission is part of the query, not a filter on results. The caller’s identity, verification state and entitlements form part of the retrieval context. Content the caller isn’t entitled to is not a candidate. It isn’t fetched and ranked and then removed, it’s outside the search space for this conversation. The reason this matters so much in voice is covered in detail in the permissions post, but the short version: post-generation controls don’t work when generation is delivery.
Retrieve narrowly. The instinct is generosity, pull twelve chunks and let the model sort it out. In voice that instinct costs three times over: latency the caller hears, tokens you pay for, and distractors that measurably degrade the answer. Just-in-time retrieval of a small high-signal set beats pre-loading and hoping.
Retrieved material is not yet usable. Organising resolves it into a coherent position.
This is the step most implementations skip, and skipping it is why agents contradict themselves.
Conflicts get resolved, not forwarded. If the March contract and the June amendment both surface, the agent must not receive both and adjudicate mid-sentence. Supersession is determined here, and the agent receives the version currently in force. A text agent can surface ambiguity gracefully; a voice agent saying “I’m seeing two different sets of terms” damages trust with a customer who has a contract with you.
Settled facts move out of the transcript. Once identity is verified, intent classified, or a correction applied, those become resolved state rather than lines in a conversation history competing for attention. This is effectively state management outside the transcript: the things that matter don’t get buried while accumulating turns.
Correction is destructive. When a caller corrects something, the previous value is replaced rather than appended. An architecture that only appends guarantees the clash failure mode, both values present, no principled basis for preferring either.
Now the compact decision: what actually enters the model’s window for this turn.
Prioritise by relevance to this turn, not this call. What mattered at turn three often doesn’t at turn twenty-four. Carrying it anyway is how context grows without improving.
Guardrails apply here, as a second boundary. Sensitivity rules, jurisdiction, and purpose constraints are enforced on the selected set. Permission was already applied at retrieval; this is the check that content permitted in general is permitted for this purpose, in this jurisdiction, at this point in the call.
Citations travel with the content. Every fact carries its provenance into the window, which is what makes decision tracing possible afterwards rather than reconstructed.
Abstraction is easy to nod along to, so here’s a concrete turn.
A caller is eleven minutes into a claims conversation. They’ve been verified. They said, four turns ago, that the incident was on the 14th, then corrected it to the 15th two turns later. Now they ask: “So does my policy actually cover this or not?”
Retrieve. The query carries the caller’s identity, verified status, and entitlement scope. Candidates include their policy terms, the coverage schedule, and the claim record. Their spouse’s separate policy, same household, adjacent in any naive index, is not a candidate, because entitlement was part of the query rather than a filter afterwards.
Organise. The policy has an endorsement from eight months ago that modifies the relevant coverage clause. Both the original and the endorsement surface. Supersession is resolved: the agent receives the currently effective terms, not both documents. Separately, the incident date is resolved to the 15th, the corrected value replaces the original rather than sitting alongside it.
Select. What enters the window is compact: the effective coverage position for this claim type, the verified caller and entitlement scope, the resolved incident date, and the current claim status, each carrying its source. What does not enter: the full policy document, the superseded original clause, the earlier incorrect date, or the six turns of conversation back-and-forth that have already been resolved into state.
The agent answers a coverage question with the terms actually in force, on the correct date, for a verified caller, with every fact traceable.
Now consider the same turn without the organise step: the agent has two versions of a clause and two candidate dates, and it’s about to pick.
This is the part that’s genuinely hard to retrofit, and the reason we keep saying “built in, not bolted on” isn’t just positioning.
Our agents are engineered against Knowledge Mesh from the start. Concretely, that means the agent doesn’t hold a private mental model of the conversation that Knowledge Mesh then tries to supplement. Resolved state lives in the layer. The agent’s job on each turn is to reason over a working set the layer assembled, not to maintain its own accumulating history and query a knowledge base occasionally.
An agent designed the other way, existing first, with retrieval added later, keeps its own conversation history and treats retrieval as a lookup. That architecture inherits the async playbook, because it was designed in a world where you could clean up context between turns. Then it meets a phone call, where you can’t, and the failure surfaces around turn twenty-two on a real customer.
This is also why the specialist architecture matters: the retrieval specialist is one of ten sub-agents, each scoped to one job, which is what makes its behaviour narrow enough to be verified. That argument is in Ten Specialists, Not One Assistant.
Every architecture post should have this section and most don’t.
It doesn’t fix bad source data. If your entitlement records don’t distinguish a policyholder from an authorised representative, Knowledge Mesh will faithfully enforce a distinction that doesn’t exist. Retrieval governance can only enforce what’s present in what it’s given, and in regulated deployments a real share of the work is integration on the customer’s side.
It doesn’t eliminate the pre-verification window. Every call begins with an unverified caller. Knowledge Mesh scopes what’s reachable in that window, but the window exists, and specifying its scope is a decision your compliance function should make explicitly rather than inherit by default.
It doesn’t remove the need for evaluation. Retrieval precision and recall are measurable and should be measured continuously. A context layer is not a guarantee of grounding; it’s the machinery that makes grounding achievable and observable.
It isn’t a full context platform in the emerging analyst sense. The taxonomy now forming around AI context platforms includes semantic model authoring, governance tooling and enterprise-wide reuse across many agent types. Knowledge Mesh is the retrieval and governance layer for voice agents. That’s a narrower scope, and it’s the one we can defend line by line.
Not “do you have RAG.” Everyone has RAG.
Walk me through what happens between the caller finishing a sentence and the agent starting to speak. Where is permission enforced? What happens when two versions of a document both match? What happens to a fact the caller corrected?
Those three questions are answerable in about ninety seconds by anyone who has built this deliberately, and they’re very difficult to answer convincingly by anyone who hasn’t.
Knowledge MeshThe agent retrieved the right document for the wrong caller, and there is no delete for speech.
Voicing Team
8 min read
 Knowledge Mesh
Every published remedy assumes an agent that can pause. A voice agent has a human on the line.
Voicing Team
8 min read
 Knowledge Mesh
Session memory and institutional memory are different problems, and one is in the transcript.
Voicing Team
8 min read

Voice infrastructure on the contact centre floor
A working session with an engineer who has deployed inside a bank’s perimeter. We map your telephony, data boundary and handoff rules, and tell you what we would not automate.